Production Down: automation scrips stuck in queued state

nothing will run in production i am on 2026.2.5.0, there is nothing that i can do to get into the /hangfile site also, it is access denied.
Recommended Answer
make sure this is 'off'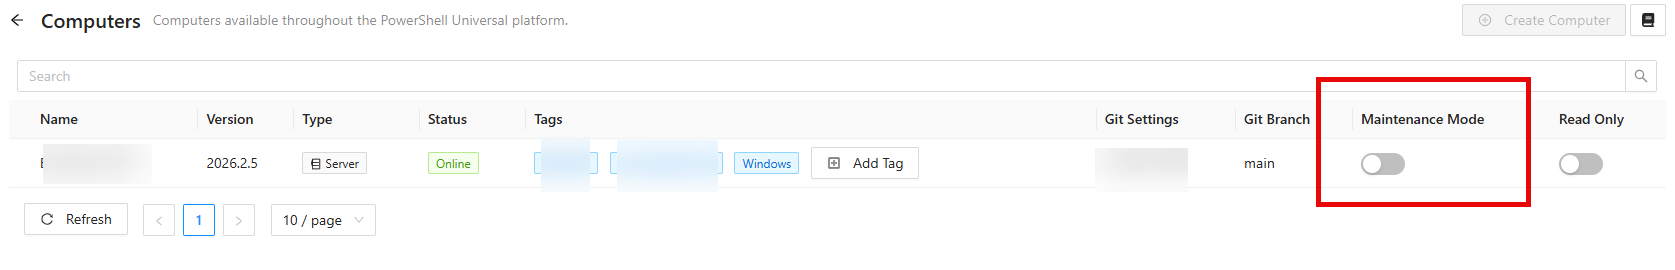
db0fa8ca-31a5-4ff3-b4bb-d0c5b834a391.png
All Comments (15)
nested site hangfire auth is bad:
https://psu.domain.com/nestedsite/hangfire
Access to psu.domain.com was denied
You don't have authorization to view this page.
HTTP ERROR 403
restarting the app pool has not helped get the jobs back into a happy state
Hello @mmorrow
Thank you for reporting this. I understand this is affecting production and that automation jobs are remaining in the Queued state on PowerShell Universal 2026.2.5.0. I also noted that recycling the IIS application pool did not restore job processing.
To help determine whether the issue is related to the Hangfire workers, queue assignment, or the persistence layer, could you please provide the following:
Is this a single PSU server or a multi-node / agent environment?
Which database provider are you using: SQLite, SQL Server, or PostgreSQL?
Are all automation jobs affected, including both manually started scripts and scheduled jobs?
Do the affected scripts use Run On, a custom queue, or a PSU Agent?
Please provide a sanitized excerpt of the PSU system log covering the application pool restart and one subsequent attempt to start a script that remains Queued. Please retain timestamps, time zone, log level, component names, exception types, stack traces, and the event sequence.
For now, please avoid making direct database changes or performing a rollback while we review the available evidence.
I also noticed that the thread includes a PSU URL. If this represents an internal hostname or private infrastructure address, please edit the post to remove or sanitize it.
Best regards,
Is this a single PSU server or a multi-node / agent environment?
- single node
Which database provider are you using: SQLite, SQL Server, or PostgreSQL?
- sqlite
Are all automation jobs affected, including both manually started scripts and scheduled jobs?
- all jobs are down
Do the affected scripts use Run On, a custom queue, or a PSU Agent?
- runs from /admin/automation/scripts
Please provide a sanitized excerpt of the PSU system log covering the application pool restart and one subsequent attempt to start a script that remains Queued. Please retain timestamps, time zone, log level, component names, exception types, stack traces, and the event sequence.
- send me a link to upload files
Since Adam is on vacation, is someone going to be able to help me?
@mmorrow
I am requesting a secure upload link so you can provide the diagnostic files without posting them publicly. As soon as I receive it, I will share it with you here.
If you prefer not to wait for the secure upload link, you can send the relevant sanitized logs and diagnostic content directly to:
ruben.tapia@ironmansoftware.com
Please do not post sensitive diagnostic files publicly. Before sending or uploading the files, please remove credentials, tokens, license keys, private keys, cookies, complete connection strings, and customer data.
Given that all automation jobs are currently unavailable in production, I am treating this as a high-priority issue and will continue reviewing the evidence as soon as it is available.
Best regards,
Ruben Tapia
Hello @mmorrow
We appreciate your patience on this case.
Here is the link to share your files:
<Sent by DM>
As soon as we receive them, I will share them with @rubentapia
Do not hesitate if you have any questions.
Best regards
Patrick Ouimet
full server reboot, did not fix it
send me a meeting invite if you want to look at it on box
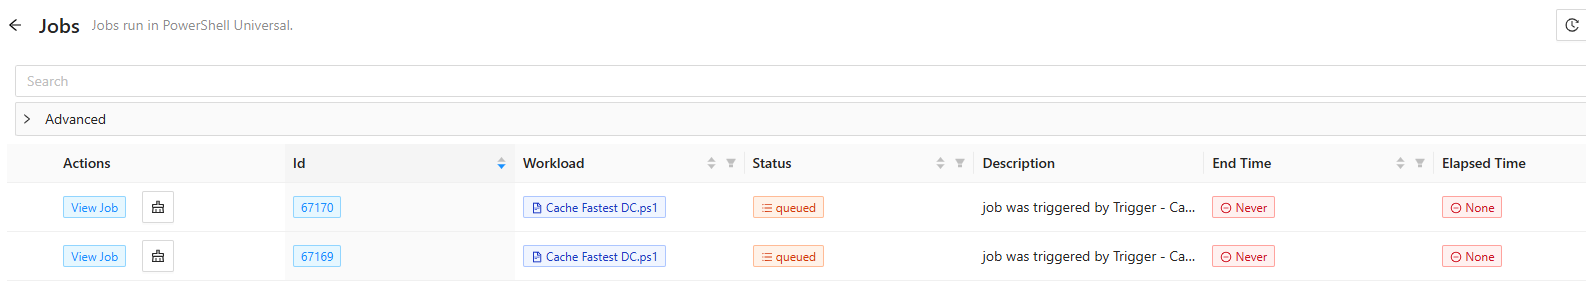
15b00f94-309f-46a1-8753-e0ad72142e27.png
@mmorrow
Thank you for sending the diagnostic files. I have received them and am actively reviewing the information.
The logs contain a repeated JobDispatcher warning indicating that no execution computers are currently available. This is relevant to the behavior you are seeing, where jobs are created successfully but remain in the Queued state. At this point, I do not want to speculate on the root cause, but we now have a concrete technical direction to investigate.
I am treating this as a critical production issue and am coordinating internally to determine why the local execution node is not being considered available and what additional diagnostic information, if any, is required.
For now, please avoid making additional configuration, database, upgrade, or rollback changes unless we specifically request them.
Thank you for your patience while we work through this.
Best regards,
its a shame that in a nested iis app that i cannot get to the /hangfire page to see if there is something in there that can be kicked
@mmorrow I understand. At this point, however, I would avoid making any changes directly through Hangfire even if the dashboard were accessible.
The diagnostic logs you provided have given us a more concrete direction. We are seeing repeated JobDispatcher warnings indicating that no execution computers are currently available, which is consistent with the jobs remaining in the Queued state.
We are reviewing this internally now to determine the safest recovery path for the production environment. I do not want to recommend retrying, deleting, or modifying queued jobs until we understand why the execution node is not being considered available.
Thank you for your patience. We are actively working on this with the information you provided.
Best regards,
need an improvement to tell us if we are in maint mode
make sure this is 'off'
db0fa8ca-31a5-4ff3-b4bb-d0c5b834a391.png